Core Idea
Cluster maintenance is three chores: upgrade the control plane before the workers with kubeadm, mind node OS upgrades, and back up both resource configs and etcd so you can restore.
- Upgrades run in order:
kubeadm upgradeon the master nodes first, then each worker, one version at a time.- A node that stays down for more than 5 minutes has its pods terminated, so plan OS maintenance around that window.
- Backups have two candidates: exported resource configuration YAML, and etcd snapshots, each with its own restore procedure.
OS Upgrades
In this section, we will take a look at OS upgrades.
If the node was down for more than 5 minutes, then the pods are terminated from that node
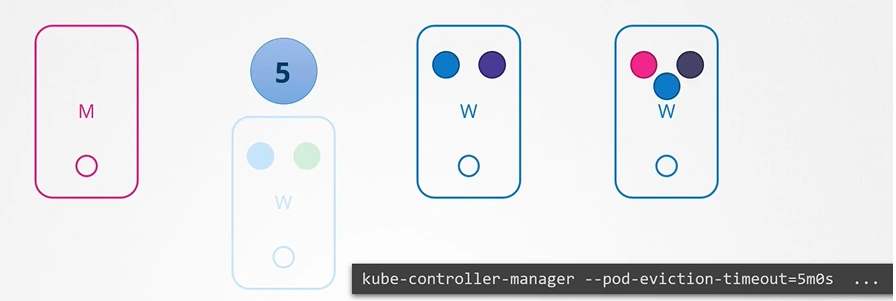
- You can purposefully
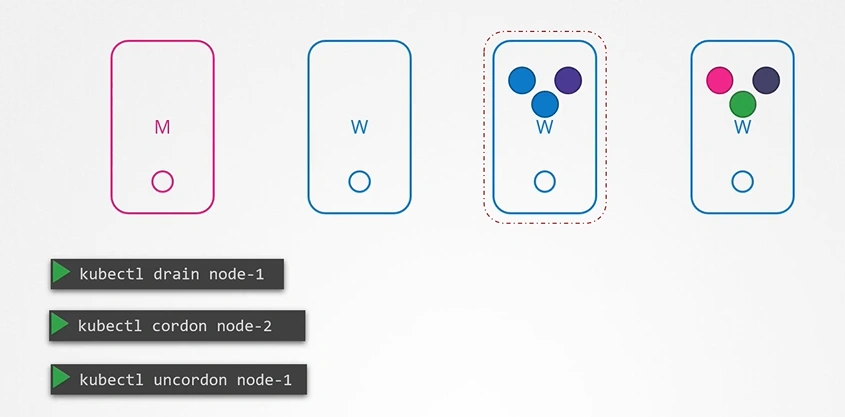
drainthe node of all the workloads so that the workloads are moved to other nodes.
kubectl drain node-1- The node is also cordoned or marked as unschedulable.
- When the node is back online after a maintenance, it is still unschedulable. You then need to uncordon it.
kubectl uncordon node-1- There is also another command called cordon. Cordon simply marks a node unschedulable. Unlike drain it does not terminate or move the pods on an existing node.
K8s Versions
In this section, we will take a look at various kubernetes releases and versions
We can see the kubernetess version that we installed
kubectl get nodes
Let’s take a closer look at the version number
First is the major version,
Second is the minor version,
Finally, the patch version
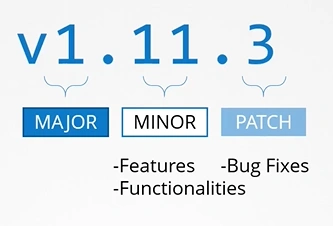
Kubernetes follows a standard software release versioning procedure
- You can find all kubernetes releases at https://github.com/kubernetes/kubernetes/releases
Downloaded package has all the kubernetes components in it except ETCD Cluster and CoreDNS as they are seperate projects.
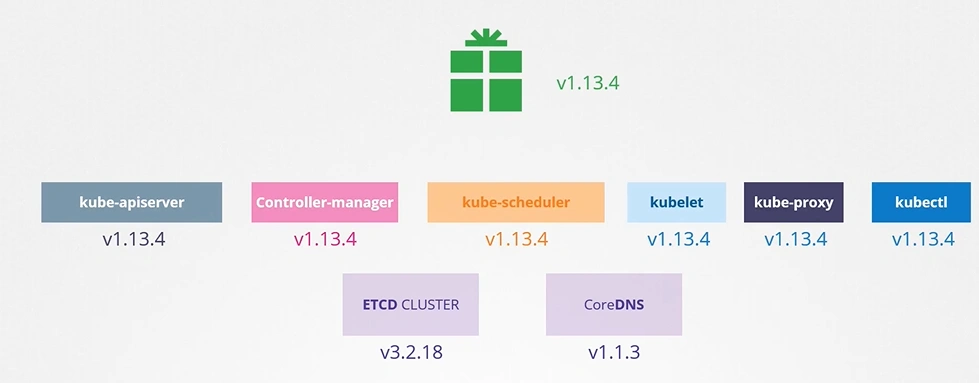
Cluster Upgrade Introduction
- Is it mandatory for all of the kubernetes components to have the same versions?
- No, The components can be at different release versions.
- At any time, kubernetes supports only up to the recent 3 minor versions
- The recommended approach is to upgrade one minor version at a time.
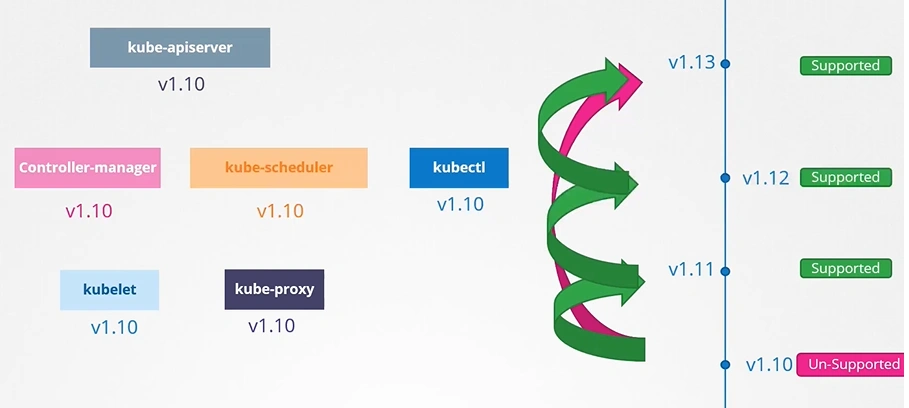
- The recommended approach is to upgrade one minor version at a time.
Options to upgrade k8s cluster
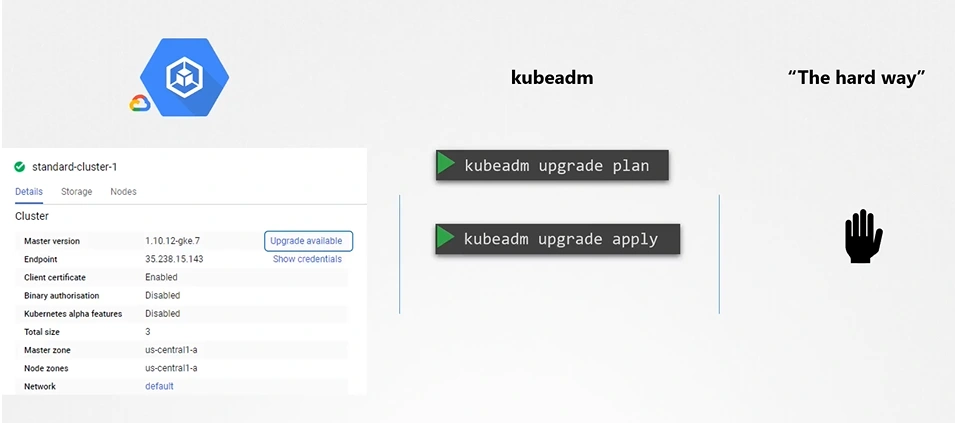
Upgrading a Cluster
- Upgrading a cluster involves 2 major steps
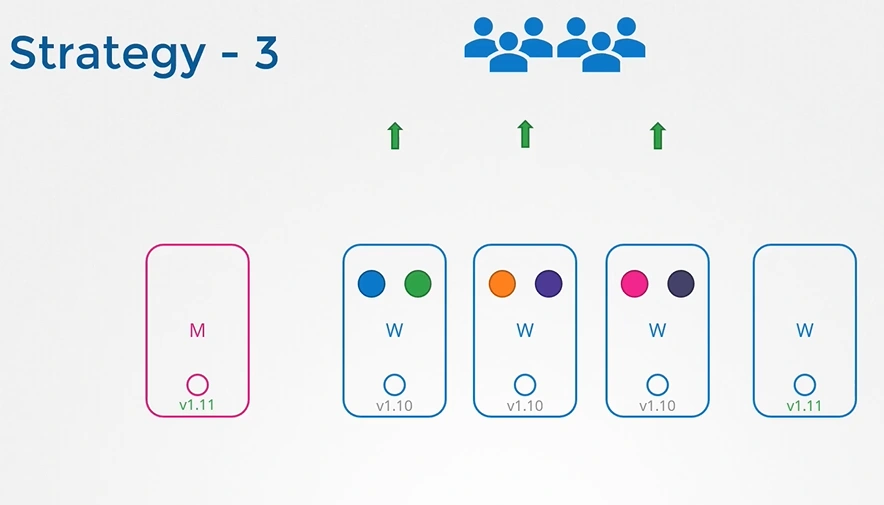
There are different strategies that are available to upgrade the worker nodes
- One is to upgrade all at once. But then your pods will be down and users will not be able to access the applications.
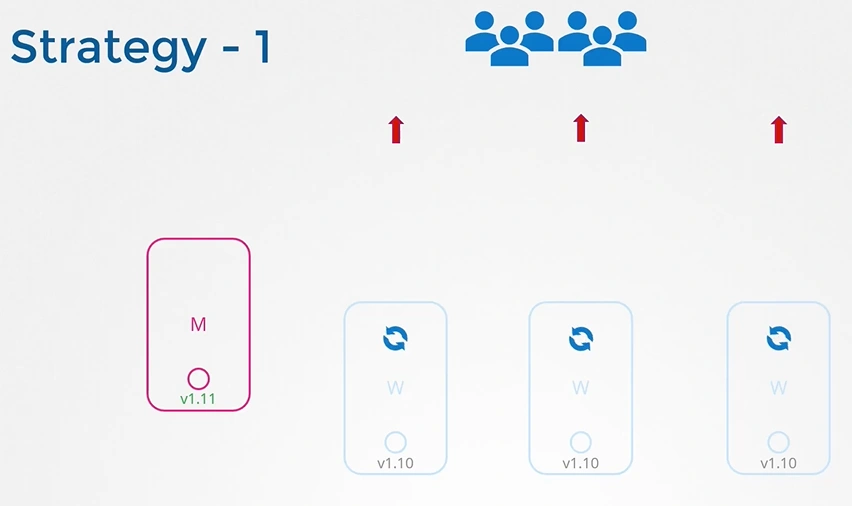
- Second one is to upgrade one node at a time.
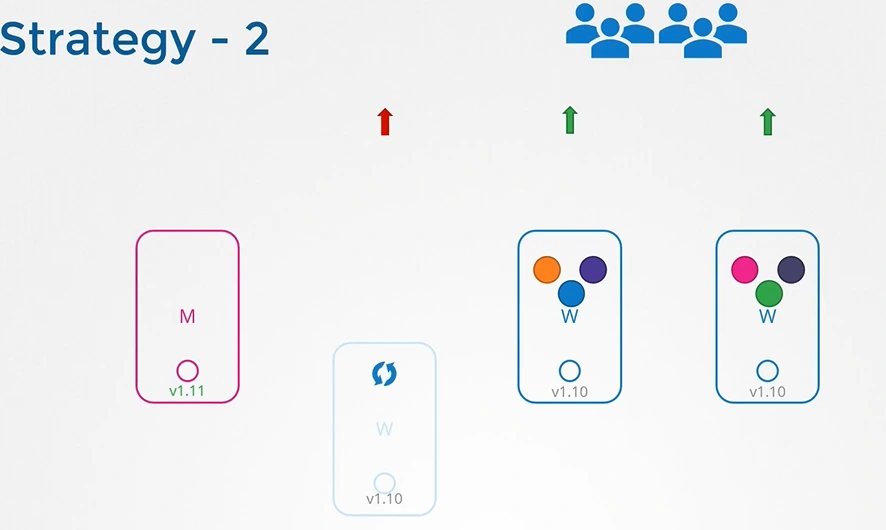
- Third one would be to add new nodes to the cluster
kubeadm - Upgrade master node
- kubeadm has an upgrade command that helps in upgrading clusters.
kubeadm upgrade plan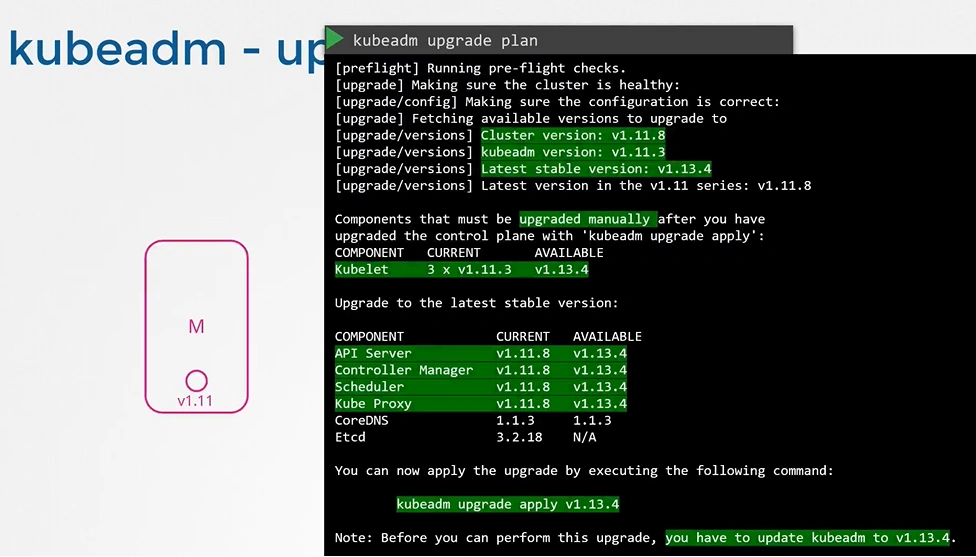
- Upgrade kubeadm from v1.11 to v1.12
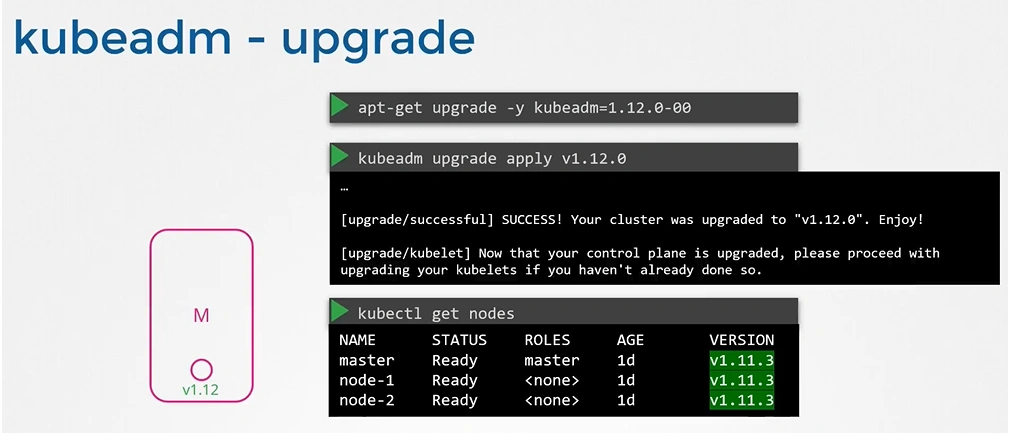
apt-get upgrade -y kubeadm=1.12.0-00
- Upgrade the cluster
kubeadm upgrade apply v1.12.0
- If you run the ‘kubectl get nodes’ command, you will see the older version. This is because in the output of the command it is showing the versions of kubelets on each of these nodes registered with the API Server and not the version of API Server itself
kubectl get nodes
- Upgrade ‘kubelet’ on the master node
apt-get upgrade kubelet=1.12.0-00
- Restart the kubelet
systemctl restart kubelet
- Run ‘kubectl get nodes’ to verify
kubectl[[Manage Node]]0 - Cluster Maintenance-20250128193922470.webp]]
## kubeadm - Upgrade worker nodes

👉 [[05317 [[Manage Node]] master node, run 'kubectl drain' command to move the workloads to other nodes
kubectl drain node-1
- Upgrade kubeadm and kubelet packages
apt-get upgrade -y kubeadm=1.12.0-00
apt-get upgrade -y kubelet=1.12.0-00
- Update the node configuration for the new kubelet version
kubeadm upgrade node config —kubelet-version v1.12.0
- Restart the kubelet service
systemctl restart kubelet
- Mark the node back to schedulable
kubectl uncordon node-1
![[05310 - Cluster Maintenance-20250128193953190.webp]]

- Upgrade all worker nodes in the same way

![[05310 - Cluster Maintenance-20250128194000933.webp]]

---
# Backup and Restore Methods

## Backup Candidates

![[05310 - Cluster Maintenance-20250128194423711.webp]]
## Backup - Resource Configs
kubectl get all —all-namespaces -o yaml > all-deploy services.yaml (only for few resource groups)
- There are many other resource groups that must be considered. There are tools like **`ARK`** or now called **`Velero`** by Heptio that can do this for you.

![[05310 - Cluster Maintenance-20250128194606213.webp]]

## Backup - ETCD

> [Operating etcd clusters for Kubernetes \| Kubernetes](https://kubernetes.io/docs/tasks/administer-cluster/configure-upgrade-etcd/)

- So, instead of backing up resources as before, you may choose to backup the ETCD cluster itself.

![[05310 - Cluster Maintenance-20250128194628094.webp]]

- You can take a snapshot of the etcd database by using **`etcdctl`** utility snapshot save command.
ETCDCTL_API=3 etcdctl snapshot save snapshot.db
ETCDCTL_API=3 etcdctl snapshot status snapshot.db
![[05310 - Cluster Maintenance-20250128194724918.webp]]
## Restore - ETCD

- To restore etcd from the backup at later in time. First stop kube-apiserver service
$ service kube-apiserver stop
- Run the etcdctl snapshot restore command
- Update the etcd service
- Reload system configs
$ systemctl daemon-reload
- Restart etcd
$ service etcd restart
![[05310 - Cluster Maintenance-20250128194749140.webp]]

- Start the kube-apiserver
$ service kube-apiserver start
#### With all etcdctl commands specify the cert,key,cacert and endpoint for authentication.
$ ETCDCTL_API=3 etcdctl
snapshot save /tmp/snapshot.db
—endpoints=https://[127.0.0.1]:2379
—cacert=/etc/kubernetes/pki/etcd/ca.crt
—cert=/etc/kubernetes/pki/etcd/etcd-server.crt
—key=/etc/kubernetes/pki/etcd/etcd-server.key
![[05310 - Cluster Maintenance-20250128194757480.webp]]
---
👉 [[ETCD#ETCDTL]]
🌟 [Velero Docs - Overview](https://velero.io/docs/v1.15/)
> [!video]- Cluster Maintenance
>
> 
> [!video]- Cluster Maintenance
>
> 