llm ai machinelearning ai/books/designingllmapplication
Tldr
The chapter’s central message is:
A language model’s capabilities depend on the combination of its data, representation, architecture, and learning objective.
The most important ideas to remember are:
Tokens → Embeddings → Transformer → Attention → Prediction → Loss → Backpropagation → Better representationsAnd for modern LLMs:
Transformer + self-attention + positional information + feedforward layers + next-token prediction is the fundamental recipe, with MoE and alternative learning objectives providing ways to improve efficiency and capability.
Neural networks and language models
1. Artificial Neural Networks (ANNs)
Modern language models are built using neural networks, which contain interconnected neurons with learnable weights/parameters.
Deep learning uses many stacked layers to learn increasingly complex patterns.
During training:
- Text is tokenized and converted into vectors.
- The vectors pass through the neural network.
- The model’s output is compared with the correct answer (ground truth).
- A loss function measures the error.
- Backpropagation + gradient descent adjust the model’s weights to reduce the loss.
Self-supervised learning
Language models are usually trained using self-supervised learning.
Unlike supervised learning, humans don’t need to manually label every example.
The training data itself provides the labels. For example, in next-token prediction, the next token already exists in the original text.
Representing meaning with vectors
Words and text are converted into numerical vectors called embeddings. (2. Tokens and Embeddings)
The goal of representation learning is for these vectors to capture useful aspects of meaning.
This is based partly on the distributional hypothesis: words with similar meanings tend to appear in similar contexts.
Distributional Hypothesis
The Distributional Hypothesis: Word Meaning from Context - Interactive | Michael Brenndoerfer
In simple terms: you can understand a word partly by looking at the words that appear around it.
What does a word mean? A philosopher might say a word refers to a concept in the mind. A logician might point to truth conditions, the set of objects in the world to which the word correctly applies. But a linguist named John Rupert Firth had a different answer, one that would eventually reshape how computers process language.
Firth’s famous observation, stated in 1957, was simple: “You shall know a word by the company it keeps.” The idea is that meaning is not some abstract property a word carries around by itself. Meaning emerges from patterns of use. Words that appear in the same kinds of sentences, surrounded by the same kinds of neighbors, tend to mean similar things. This is the distributional hypothesis, and it is the theoretical foundation for nearly everything in modern NLP, from bag-of-words models to word2vec to transformer language models.
The Transformer architecture
Attention is All You Need (Transformers) > Transformer
Transformers became dominant because they solve important limitations of older recurrent models such as LSTMs, especially difficulties with long-range dependencies.
A Transformer consists of stacked Transformer blocks, mainly containing:
- Embeddings — convert tokens into vectors.
- Self-attention — lets each token consider other relevant tokens in the sequence.
- Positional encoding — provides information about token positions.
- Feedforward networks — transform token representations and learn nonlinear patterns.
- Layer normalization — improves training stability and convergence.
Self-attention
Self-attention is one of the most important Transformer mechanisms.
For each token, the model creates:
- Query (Q)
- Key (K)
- Value (V)
The model:
- Compares a token’s query with other tokens’ keys.
- Calculates attention scores.
- Scales the scores.
- Uses softmax to convert them into weights.
- Combines the value vectors according to those weights.
This allows the model to determine which other tokens are important for understanding each token.
Example:
“Mark told Sam that he was planning to resign.”
Attention can help the model connect “he” with “Mark”.
Using multiple sets of Q, K, and V is called multi-head attention, allowing the model to learn different relationships simultaneously.
Positional Encoding
Unlike LSTMs, Transformers process tokens largely in parallel, so they need a way to know where tokens occur.
Common approaches include:
- Absolute positional embeddings
- ALiBi
- RoPE (Rotary Position Embeddings)
- No positional encoding
Modern LLMs commonly use RoPE or ALiBi.
Feedforward networks and normalization
After attention, each token passes through a feedforward neural network, usually with nonlinear activation functions such as ReLU or GELU.
Layer normalization keeps activations well-behaved and makes training more stable and efficient.
Loss and perplexity
For next-token prediction, the model produces probabilities for every token in its vocabulary.
The most common loss is cross-entropy:
Cross-entropy = −log(probability assigned to the correct token)
So, if the model gives the correct answer a high probability, the loss is low.
A common evaluation metric is perplexity:
Perplexity = 2^cross-entropy
- Lower perplexity = better next-token prediction.
- Perplexity of 1 means perfect prediction.
Three major Transformer architectures
| Architecture | Main use |
|---|---|
| Encoder-only | Understanding, classification, embeddings |
| Encoder-decoder | Text-to-text tasks such as translation |
| Decoder-only | Text generation and general-purpose LLMs |
| Examples: |
- BERT/RoBERTa → encoder-only
- T5 → encoder-decoder
- GPT-style models → decoder-only
Decoder-only models have become dominant for general-purpose LLMs because they are particularly strong at zero-shot and few-shot learning.
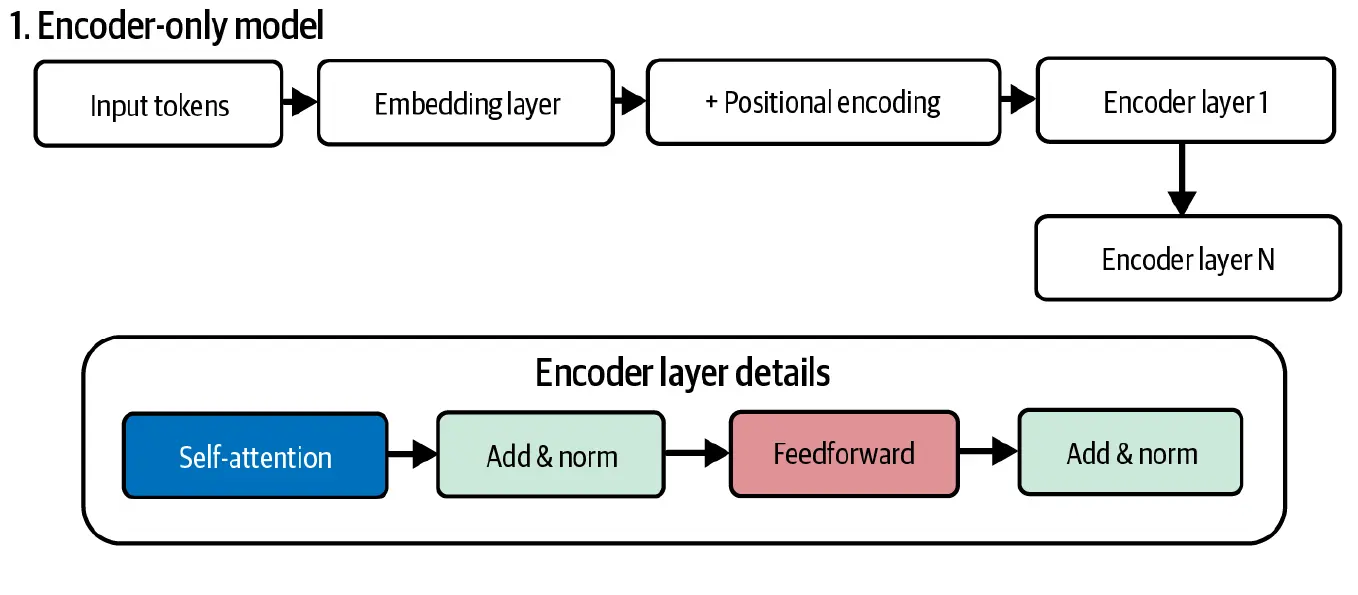
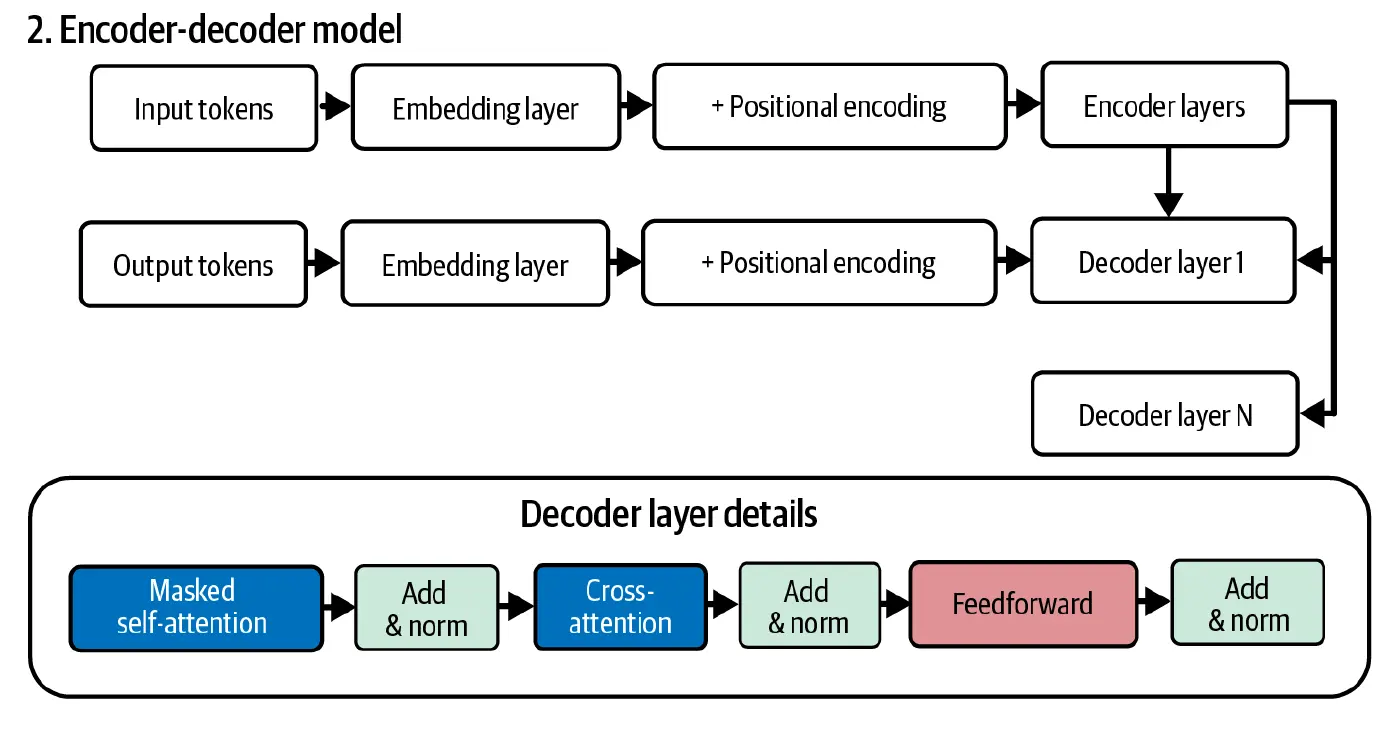
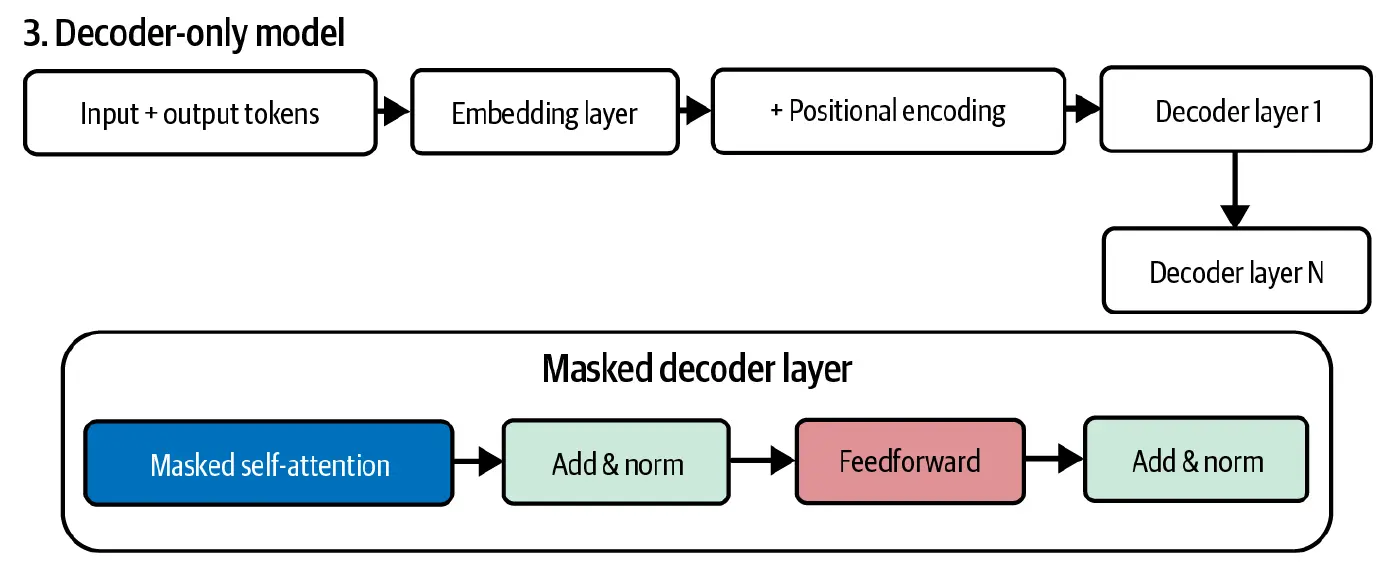
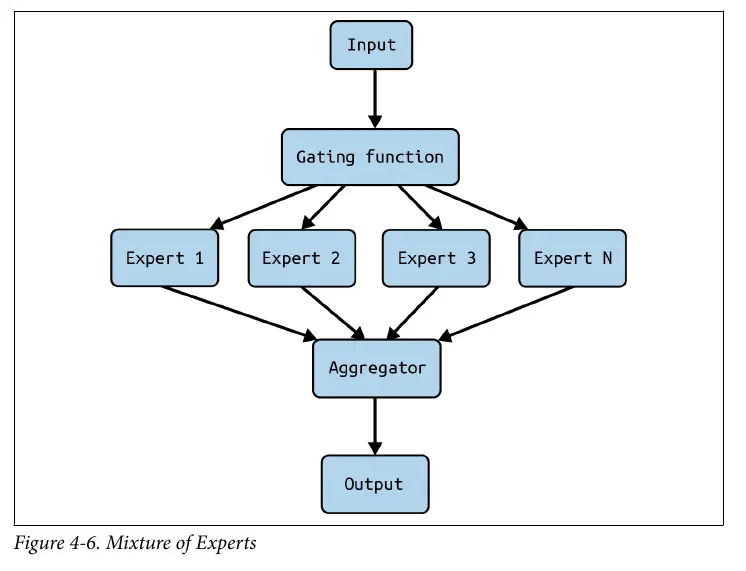
Mixture of Experts
Main learning objectives
The chapter discusses three major approaches:
Full Language Modeling (FLM)
The model predicts the next token.
“Language models are ___”
The model might predict “ubiquitous.”
This is the dominant approach for many modern generative LLMs because every token can provide a training signal.
Masked Language Modeling (MLM)
Some tokens are hidden and the model must reconstruct them.
“Tempura ___ been a source ___ in the family.”
The model predicts the missing words.
This approach is associated with models such as BERT and is particularly useful for understanding/classification tasks.
Prefix Language Modeling (PrefixLM)
The model receives a prefix that can use bidirectional context, while the remaining suffix is predicted autoregressively.
Denoising objectives
MLM can be viewed as a denoising autoencoder: corrupt the input, then train the model to reconstruct the original.
Models such as T5 and BART use variations involving:
- Masking tokens
- Deleting tokens
- Masking spans
- Shuffling documents
- Rotating documents
UL2 combines several objectives through a Mixture of Denoisers, attempting to get benefits from multiple training approaches.
Why next-token prediction is powerful
Although next-token prediction sounds simple, successfully doing it requires the model to learn many underlying patterns.
To predict:
“Tammy jumped over the ___”
the model needs knowledge about: Grammar, Vocabulary, Context, Common relationships between words, Potentially facts and concepts
After seeing billions of examples, the model can develop increasingly sophisticated internal representations.
However, the chapter emphasizes that whether next-token prediction alone is sufficient for general intelligence remains an open question.
Pre-training and domain-specific models
The chapter ends with an important experiment involving chess.
A model was trained from scratch using:
- A chess-game dataset
- A Transformer
- Next-token prediction
- A vocabulary designed specifically for chess notation (PGN)
The model learned aspects of chess—including game rules—without being explicitly taught the rules in natural language.
Interestingly, a model trained on English descriptions of the same chess games performed worse.